Solve Markov Decision Processes with the Value Iteration Algorithm - Computerphile
Introduction to Reinforcement Learning: Towards Physical AI
CS825 lecture 7.3 - Value iteration
Value Iteration
Value Iteration Explained | Dynamic Programming in Reinforcement Learning
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 30, 2026
Conclusion
For 2026, 37 Value Iteration remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
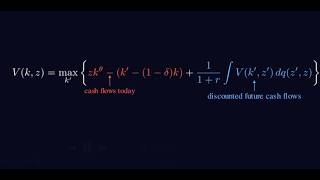
In this video the following topics covered: 1. Calculation of Bellman equation 2. Here we introduce dynamic programming, which is a cornerstone of model-based reinforcement learning. We demonstrate ... For more information about Stanford's Artificial Intelligence professional and graduate programs, visit: stanford.io/ai Andrew ... This is the visualizer that lets you visualize policy This is the first of three videos in the series: Geometric Intuition for Structural Estimation. Produced using the Manim Python library ... Returning to the Markov Decision Process, this time with a solution. Nick Hawes of the ORI takes us through the algorithm, strap in ... ... 23:52 Policy Evaluation (Pseudo Code) 24:51 Policy Iteration (Pseudo Code) 26:28 ... to show you a method called Prof. Abbeel steps through the execution of