Looking for the latest information on Bert Language Model How To Train Bert? We've compiled comprehensive data, records, and insights about Bert Language Model How To Train Bert.
Main Features
Explore the main sources for Bert Language Model How To Train Bert.
Recent Updates
Stay updated on Bert Language Model How To Train Bert's newest achievements.
Lec 18 | Pre-Training Strategies: ELMo, BERT
Transformer models and BERT model: Overview
Fine-Tuning BERT for Text Classification (w/ Example Code)
BERT: Masked Language Modeling (Natural Language Processing at UT Austin)
Language Processing with BERT: The 3 Minute Intro (Deep learning for NLP)
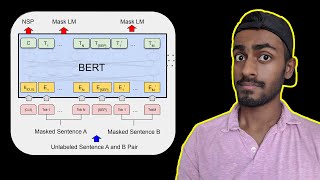
BERT Transformer: Pretraining and Fine Tuning
BERT explained: Training, Inference, BERT vs GPT/LLamA, Fine tuning, [CLS] token
Stanford CS224N: NLP with Deep Learning | Winter 2020 | BERT and Other Pre-trained Language Models
Transformer and BERT Pre-training
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
LLM Fine-Tuning 09: Fine-Tuning BERT for NLP (NER, Sentiment, QA) | Hugging Face #huggingface #llm
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 29, 2026
Final Thoughts
For 2026, Bert Language Model How To Train Bert remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Bidirectional Encoder Representations from Transformers ( Encoder-Only Transformers are the backbone for RAG (retrieval augmented generation), sentiment analysis and classification ... tl;dr: This lecture explores the critical pre- Watch this video to learn about the Transformer architecture and the Bidirectional Encoder Representations from Transformers ... Connect on LinkedIn: linkedin.com/in/shawhintalebi/ In this video, I walk through how to fine-tune Part of a series of video lectures for CS388: Natural Since its introduction in 2018, the This is a recorded presentation in York University for the published paper of " For more information about Stanford's Artificial Intelligence professional and graduate programs, visit: stanford.io/3waBO2R ... In this lecture we look at the Transformer architecture for sequence contextualization, how the arxiv.org/abs/1810.04805 Abstract: We introduce a new