Looking for the latest information on Llama Cpp Windows Cmake? We've researched comprehensive data, records, and insights about Llama Cpp Windows Cmake.
Core Information
Explore the key sources for Llama Cpp Windows Cmake.
History
Stay updated on Llama Cpp Windows Cmake's newest achievements.
GPU Specific llama.cpp Compilation: Massively Reduce Build Times
The easiest way to run LLMs locally on your GPU - llama.cpp Vulkan
Building llama.cpp from source
How to Install Llama.cpp on Windows 11 (CUDA 13 & RTX 50-Series Guide)
Llama.cpp vs vLLM: Which Local LLM Engine Actually Scales
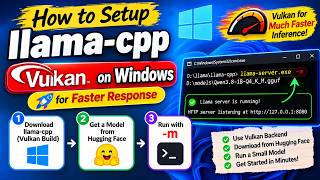
Set Up llama-cpp-server on Windows with Vulkan: Run a Small AI Model Locally
Como Rodar Seu Próprio ChatGPT LOCALMENTE! Llama.cpp Tutorial (Fácil e Rápido)
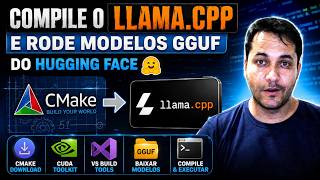
Como Compilar o Llama.cpp no Windows e Rodar Modelos GGUF do Hugging Face | CUDA + CMake
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 31, 2026
Conclusion
For 2026, Llama Cpp Windows Cmake remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
In this tutorial, I show you how install and use Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... Using GPU specific compilation vastly speed up local In this video, we're setting up Learn more about Large Language Models (LLMs) here → ibm.biz/~uLCBj5HLQ Choosing a local LLM engine can make ... Aprenda como instalar e compilar o Neste vídeo, mostro passo a passo como instalar o