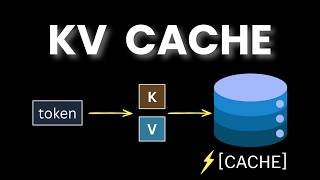
KV Cache in LLMs Explained Visually | How LLMs Generate Tokens Faster
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 30, 2026
Summary
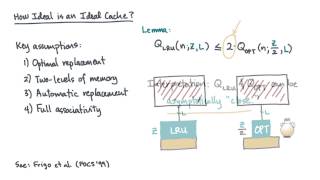
For 2026, The Ideal Cache Model remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
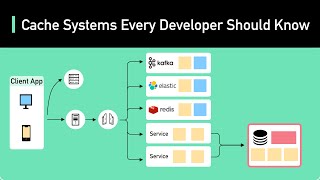
This video is part of the Udacity course "High Performance Computing". Watch the full course at ... Shun discusses associativity in caches, Ready to become a certified watsonx Generative AI Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... Learn more about LLM inference here → ibm.biz/~Ewjm0UejN Why do LLMs crawl when traffic spikes? Legare Kerrison ... Get a Free System Design PDF with 158 pages by subscribing to our weekly newsletter.: blog.bytebytego.com Animation ... Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io The KV In this deep dive, we'll explain how every modern Large Language Digital Design and Computer Architecture, ETH Zürich, Spring 2025 ( safari.ethz.ch/ddca/spring2025/) Lecture 22: Ever wondered how large language MIT 6.046J Design and Analysis of Algorithms, Spring 2015 View the complete course: ocw.mit.edu/6-046JS15 Instructor: ...